Cloudflare's GLM-5.3 Launch Went Wrong and the Model Wasn't the Problem
GLM-5.3 is a cheap, capable coding model from Z.ai. Its first weeks on Cloudflare's Workers AI were marked by a leak caused by a deployment and testing failure. Here is what happened and what to do.
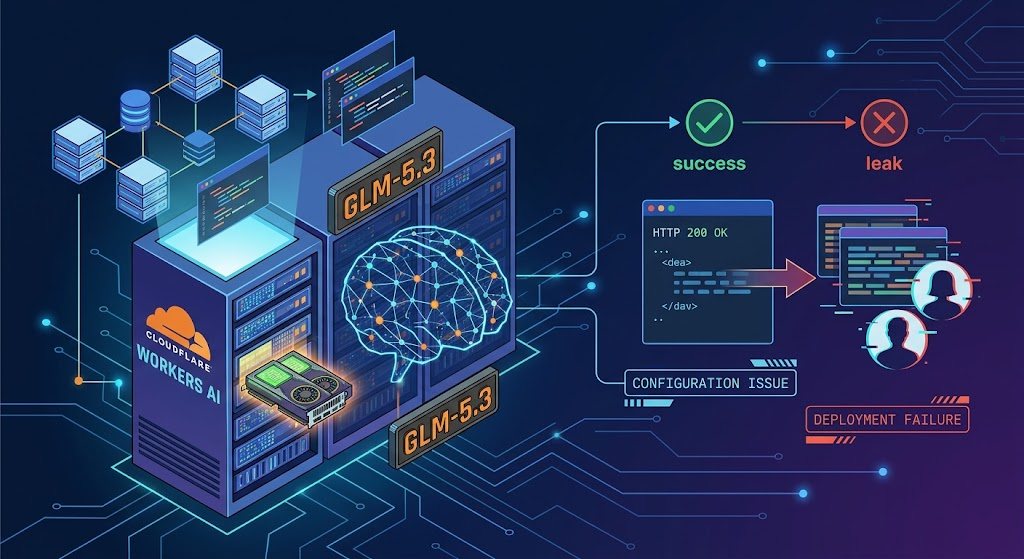
Every developer knows the small chill of a green checkmark you can't quite trust. For about two weeks, a success code hid a problem: 155 replies to extra-long prompts carried pieces of other customers' sessions. The story is not about a flawed model but about how it was launched and tested.
GLM-5.3 is Z.ai's text-generation model built for agentic coding workflows, and Cloudflare offers it on Workers AI.
The leak ran from August 27 to September 9, 2026, according to Cloudflare's October 26 incident report. Our take: the cause was not the model or an attack, but a configuration choice combined with a bug in the inference engine. The model weights played no role.
So what exactly is GLM-5.3?
Z.ai was known as Zhipu AI until it rebranded internationally in July 2025, and the company grew out of a research group at Tsinghua University. The GLM family began in December 2021 as a bilingual Chinese-English model project. GLM-5.3 launched on August 14, 2026, and Z.ai's model card says it is built on the base model behind GLM-5.2, with every gain coming from post-training.
Under the hood, it is a mixture-of-experts model, meaning only a slice of its parameters, about 40 billion, work on each token. The weights arrived on Hugging Face by August 31, 2026 under a custom Z.ai license rather than MIT.
On Workers AI, Cloudflare runs the model on its own GPUs, so developers call it by name instead of managing hardware.
What actually went wrong on September 9?
The trouble began with a mismatch that was known before launch. The model launched with a context window of 1,048,576 tokens, but the cache on its prefill GPUs had room for only 681,280. The team knew and judged it harmless, because its long-context tests returned successful responses.
Then the engine bug turned that gap into a leak. In SGLang's disaggregated mode, over-length requests were marked rejected, swapped for a one-token placeholder and passed on, and the decoder read stale cache pages from earlier requests. Clients got HTTP 200 instead of an error. Another user had flagged the flaw publicly on July 6, 2026, so the warning existed long before the leak was caught. That is why a green status code is not proof of a healthy response.
Once a researcher flagged the leak, the response took a single day. Security researcher Gadi Evron of Knostic reported it through HackerOne on September 8, 2026. Verification started at 08:00 UTC the next day, and an incident was declared at 13:22 after the leak was reproduced with two accounts. The model went private at 14:00 and came back at 19:40 UTC. The fix was quick once someone reported the problem, but the leak itself ran undetected for about two weeks.
How long the model was down depends on who is counting. Some counts put the offline period at roughly 20 hours, but that clock runs from the report, while Cloudflare's own times are the ones that measure the outage. The fix was tested against the researcher's own reproduction and its canary-marker tests before the model returned that evening, and the SGLang project was told the same day.
By the numbers
- 155: responses confirmed affected, all to prompts over 681,280 tokens
- 1,048,576: tokens in the GLM-5.3 context window
- 128K: tokens of maximum output
- 2.04 million: tokens the prefill pool now holds
- 14:00 to 19:40 UTC: the model's time offline on September 9, 2026
- 1: model affected, since other deployments have larger cache pools
Why is this all surfacing now?
The full story arrived late. The report came about seven weeks after the fix. That landed after the model's launch buzz and a safety assessment from CAISI, part of the U.S. standards body NIST. More is coming, because the researcher's own report on discovery and validation is due later.
CAISI found GLM-5.3 to be the most cyber-capable open-weight model released to date, though its cyber skills sit significantly below current U.S. frontier models. Its estimate is a lag of about four months, and it rated GLM-5.3 above Kimi K3. That assessment is part of why the story arrived when it did.
The debate split along familiar lines. OpenAI's Greg Brockman warned that the open-weight model is likely to speed up the threat landscape, while former Department of Defense analyst Jake Williams argued attackers already hold comparable tools. Both camps look overheated, since CAISI's own verdict sits between them. For you, that means choosing a model on how it performs and how it is deployed, not on the loudest security headline.
Is it any good, and is it cheap?
The glossiest numbers are Z.ai's own. Its model card claims a 50% improvement on its in-house Code Bench, yet the lab itself reports that Fable 5 still leads. Independent scoring is humbler, so trust outside tests over the launch page.
Against Kimi K3, the closest rival, it is nearly a tie. Kimi K3 wins 5 of 9 shared benchmarks and also accepts images, which GLM-5.3 does not. The context window is identical, and Kimi K3 is far larger in parameters.
Price is where GLM-5.3 pulls ahead. Z.ai's own list price is $1.40 per million input tokens, and the model comes out roughly 3.0x cheaper per token than Kimi K3. List prices understate long agent runs, though, since a max-effort task costs more than a low-effort one.
One gap matters here: the evidence holds no Workers AI price for GLM-5.3, and the comparison page does not list Workers AI at all. The cost edge is likely real at Z.ai's prices and unproven on Workers AI.
What it means if you build on Workers AI
Our read is that GLM-5.3 suits teams building coding agents or code-review pipelines who want a strong open model without managing GPUs. Self-hosting is the alternative, and it needs at least 8 GPUs of H200 class or better, so it only makes sense if you want control over your own hardware. It fits less well for sensitive data at extreme context lengths, for teams that need vision, or for buyers with PRC-vendor procurement limits.
A few habits help. Send an x-session-affinity header for agent sessions, cap prompt length in your own gateway, and check output content rather than only status codes. The incident report is the place to check whether your account was among the affected requests.
Serverless capacity is shared, and there is no strict guarantee of processing. That matters because the async API is the recommended route for durable workflows, so teams with long-running jobs should start there. Before adopting, check the current Workers AI pricing page and benchmark the model on your own tasks.
Where this is heading
We think GLM-5.3 is a credible low-cost coding model a step behind closed frontier models. The count of affected responses shows limited harm, not that harm was ruled out.
The base case is steady growth among cost-sensitive coding agents, as long as the larger cache pool and the SGLang v0.5.22 fix hold up. The risk is that further details erode trust and cautious enterprises drift to closed or other hosted models. Watch for any revision of the affected count and for changes to how the model is tested.
On capability, another quick Z.ai release may come, and CAISI's four-month lag is a snapshot. The custom license and the staged release could shape who adopts it. Your next check: a published Workers AI price, the researcher's report and new CAISI results.
Sources 12unite.ai, BigGo Finance, Cloudflare and 9 more sources
- unite.ai (Oct 26, 2026). Cloudflare Says GLM-5.3 Bug Leaked 155 Responses Across Tenant Sessions. Miles Okada
- BigGo Finance (Oct 27, 2026). Cloudflare Confirms AI Platform Data Leak: 155 Responses Mixed With Other Users' Requests, Ultra-Long Contexts Blamed — BigGo Finance. BigGo Finance
- Cloudflare (Oct 26, 2026). Cross-request KV cache exposure in the GLM-5.3 Workers AI model (155 responses)
- LLMLearner (Sep 5, 2026). GLM-5.3 Benchmark Results Analysis & Model Comparisons
- explainx.ai (Jun 29, 2026). GLM-5.3 Vision: Zhipu Community Wishlist Explained. Yash Thakker
- Turing Post (May 4, 2024). Zhipu AI (Z.ai): Founders, GLM Models, and Hong Kong IPO. Ksenia Se
- Tech AI Wire (Aug 31, 2026). GLM-5.3 weights ship under a custom license and need eight .... Tech AI Wire Team
- NIST (Sep 17, 2026). CAISI’s Assessment of Z.ai’s GLM-5.3 Cyber Capabilities
- lmsys.org (Oct 26, 2026). SGLang security update: improving request isolation - LMSYS Org
- Emergent (Aug 20, 2026). GLM 5.3 Review: What the AI Community Is Actually Saying
- LLM Stats (Aug 14, 2026). GLM-5.3 vs Kimi K3: Benchmarks, Pricing & Which Is Better in 2026. LLM Stats
- Cloudflare (Mar 19, 2026). Powering the agents: Workers AI now runs large models, starting with Kimi K2.5. Michelle Chen
Last updated 27 Oct 2026. This article draws on reporting and data from these sources; links in the text point to the most important ones.
Comments
No comments yet. Be the first to say what you think of this post.