
Crawlbase
Web crawling and scraping infrastructure with a crawling API, rotating proxy, managed scrapers and an MCP server.
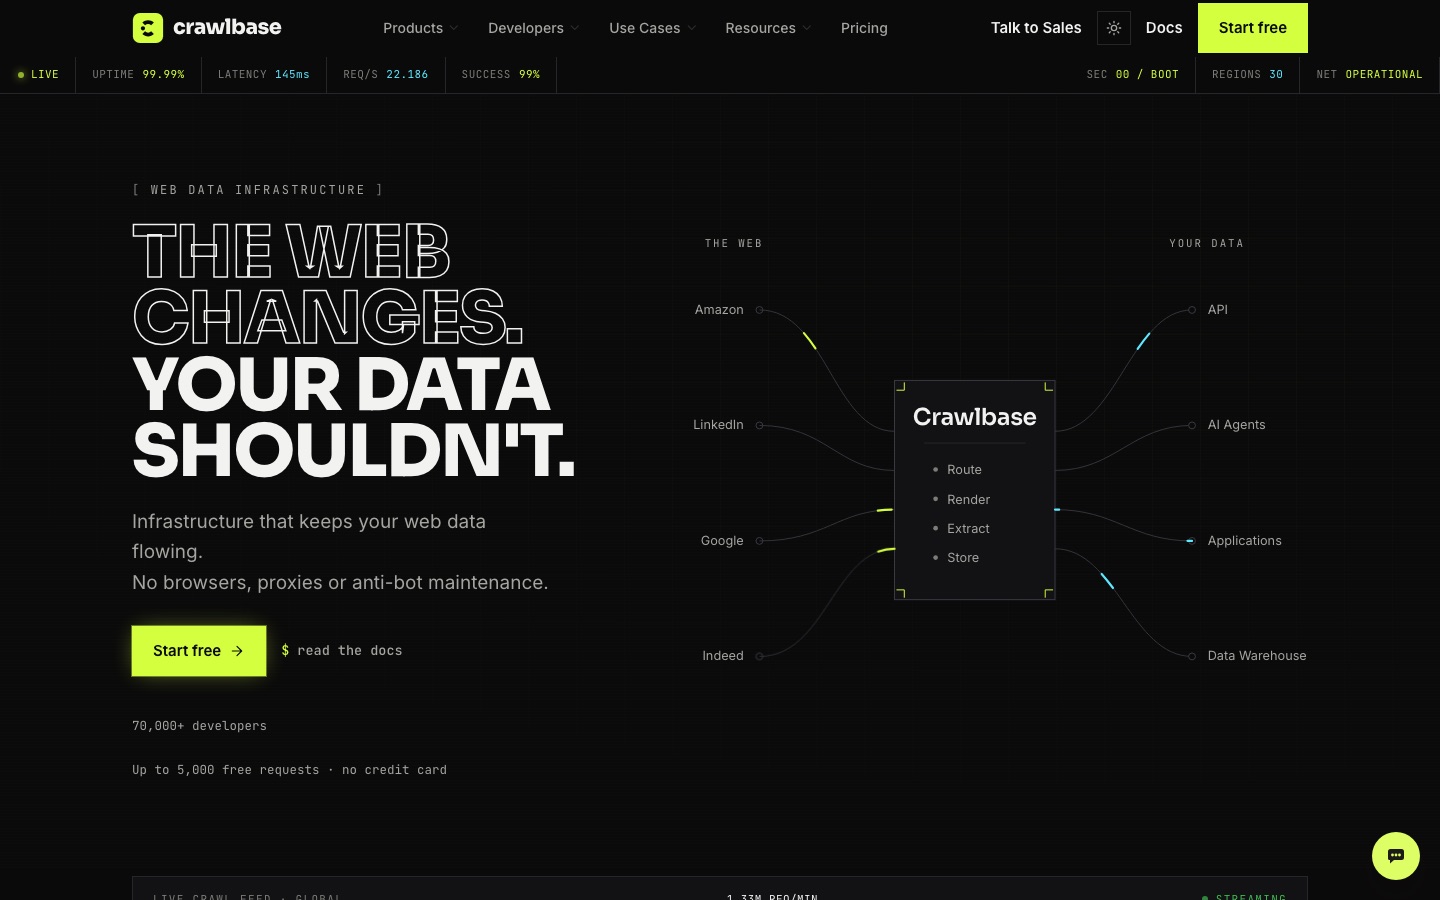
Crawlbase is a web data platform for developers and AI teams. Crawlbase accepts a URL through its API and returns HTML or structured JSON, handling proxy rotation, JavaScript rendering and anti-bot checks on its side. It also offers an asynchronous crawler, a proxy endpoint, cloud storage and an MCP server for AI agents.
Best for Developers and data teams that need web pages fetched and parsed reliably at volume without running their own proxies and headless browsers.
- Platforms
- API, MCP
- Pricing model
- Credits
- Free plan
- Yes
- API
- Yes
- Made by
- Crawlbase
- Added
Last verified: . Information taken from crawlbase.com.
What is Crawlbase?
Crawlbase is web data infrastructure that fetches and parses public web pages on behalf of developers, enterprises and language-model applications. Its Crawling API takes a URL and a token and responds with HTML, Markdown or structured JSON, rendering pages in a real browser when JavaScript is needed. The Enterprise Crawler processes very large URL batches asynchronously and delivers results by callback, while Smart AI Proxy exposes rotating residential and datacenter IPs across 30 geographies behind one endpoint. Managed scrapers return typed fields for sites such as Amazon, Google and LinkedIn, Cloud Storage keeps crawled pages for later retrieval, and the Web MCP Server lets AI agents request live pages over the Model Context Protocol. SDKs cover Python, Node, Go, Ruby, PHP, Java and .NET. All products draw on one credit balance, and only successful requests are billed.
Key Features
Crawling API
Returns clean HTML or parsed data for a submitted URL, with rendering and anti-bot handling included.
Enterprise Crawler
Queues millions of URLs and pushes results to your callback without you running workers.
Smart AI Proxy
Routes requests through automatically rotated residential and datacenter IPs via a single proxy endpoint.
Managed scrapers
Extracts structured fields from specific high-demand sites and is updated by Crawlbase when those sites change.
Cloud Storage
Saves crawl results so a page can be fetched again from storage instead of from the source.
Web MCP Server
Gives AI agents and RAG pipelines access to current web pages through MCP.
Use Cases
- Price and product monitoring
- Collect product details and prices from e-commerce sites on a schedule.
- Search results tracking
- Gather search engine result pages in large numbers.
- Market intelligence
- Compile catalogue and review data from marketplaces and directories.
- Data for AI applications
- Supply models and retrieval pipelines with fresh web content.
- Workflow automation
- Trigger crawls from n8n, Zapier or Scrapy integrations.
Things to know
- Rendering and hard sites cost more
- JavaScript rendering doubles a request's credit cost, and heavily defended sites carry difficulty multipliers that go as high as 20 times.
- Storage and screenshots use credits
- Keeping a page in storage costs 0.5 credits per month and a screenshot costs 2 credits, taken from the same balance.
- Subscription credits reset monthly
- A subscription's credit block resets each cycle; usage beyond it continues at pay-as-you-go rates unless that is switched off.
FAQs
What is Crawlbase?
Crawlbase is web data infrastructure that crawls and scrapes websites and returns clean or structured data through one platform.
How does the Crawlbase API work?
You send a URL with your token; Crawlbase routes it through a rotating proxy, renders JavaScript if required, deals with CAPTCHAs and bot checks, and returns the data.
Is Crawlbase free?
Crawlbase has a free tier: new accounts get 1,000 free credits without a card, rising to as many as 5,000 after completing setup steps.
How much does Crawlbase cost?
Crawlbase: a free plan is available. Paid plan rates are published on crawlbase.com. Check the official pricing page for current amounts.
Does Crawlbase have an API?
Yes. Crawlbase is built around an HTTP API, with a proxy interface, an MCP server and official SDKs for seven languages.
Am I charged for failed requests on Crawlbase?
No. Crawlbase bills only successful requests; failed or blocked ones cost nothing.
Can Crawlbase be used with AI agents?
Yes. The Crawlbase Web MCP Server provides live web data to AI agents and LLMs through the Model Context Protocol.
Who it's for
- Developers
- Data engineers
- AI teams
- E-commerce analysts
- Enterprises
Comments
No comments yet. If you have used Crawlbase, tell other readers how it went.
Alternatives to Crawlbase
| Tool | Free plan | Starting price | API |
|---|---|---|---|
 Context.devWeb scraping API for AI agents that returns pages as Markdown, HTML, screenshots or structured data, with crawling and monitoring. |
Yes | — | Yes |
 FirecrawlWeb data API that searches, scrapes, crawls and interacts with websites and returns clean output for AI applications. |
Yes | $16/mo | Yes |
ScrapingBeeWeb scraping API that handles proxies, headless browsers and AI-based data extraction for you. |
— | — | Yes |
 Axiom.aiBrowser automation and web scraping tool with a no-code Chrome extension, developer APIs and an MCP server. |
— | — | Yes |
 Elastic StackSuite built around Elasticsearch for search, observability and security, with vector search and AI agent tooling. |
— | — | Yes |
Listed in the same categories as Crawlbase. A starting price appears only where we checked it on the maker’s pricing page; a dash means not checked or not published. All Web Scraping & Data Extraction tools